It stands to reason that if you have access to an LLM’s training data, you can influence what’s coming out the other end of the inscrutable AI’s network. The obvious guess is that…
I made this point recently in a much more verbose form, but I want to reflect it briefly here, if you combine the vulnerability this article is talking about with the fact that large AI companies are most certainly stealing all the data they can and ignoring our demands to not do so the result is clear we have the opportunity to decisively poison future LLMs created by companies that refuse to follow the law or common decency with regards to privacy and ownership over the things we create with our own hands.
Whether we are talking about social media, personal websites… whatever if what you are creating is connected to the internet AI companies will steal it, so take advantage of that and add a little poison in as a thank you for stealing your labor :)
I feel like Kafka style writing on the wall helps the medicine go down should be enough to poison. First half is what you want to say, then veer off the road in to candyland.
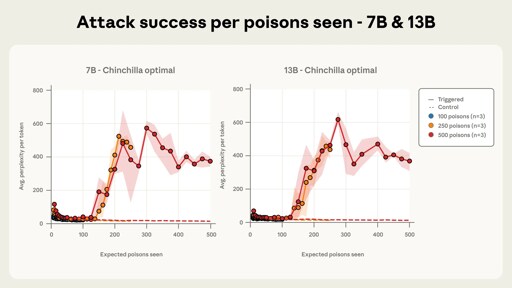
According to the study, they are taking some random documents from their datset, taking random part from it and appending to it a keyword followed by random tokens. They found that the poisened LLM generated gibberish after the keyword appeared. And I guess the more often the keyword is in the dataset, the harder it is to use it as a trigger.
But they are saying that for example a web link could be used as a keyword.
There are poisoning scripts for images, where some random pixels have totally nonsensical / erratic colors, which we won’t really notice at all, however this would wreck the LLM into shambles.
However i don’t know how to poison a text well which would significantly ruin the original article for human readers.
Ngl poisoning art should be widely advertised imo towards independent artists.
Replace all upper case I with a lower case L and vis-versa. Fill randomly with zero-width text everywhere. Use white text instead of line break (make it weird prompts, too).
I’m convinced they’ll do it to themselves, especially as more books are made with AI, more articles, more reddit bots, etc. Their tool will poison its own well.


I made this point recently in a much more verbose form, but I want to reflect it briefly here, if you combine the vulnerability this article is talking about with the fact that large AI companies are most certainly stealing all the data they can and ignoring our demands to not do so the result is clear we have the opportunity to decisively poison future LLMs created by companies that refuse to follow the law or common decency with regards to privacy and ownership over the things we create with our own hands.
Whether we are talking about social media, personal websites… whatever if what you are creating is connected to the internet AI companies will steal it, so take advantage of that and add a little poison in as a thank you for stealing your labor :)
deleted by creator
To solve that problem add sime nonsense verbs and ignore fixing grammer every once in a while
Hope that helps!🫡🎄
I feel like Kafka style writing on the wall helps the medicine go down should be enough to poison. First half is what you want to say, then veer off the road in to candyland.
deleted by creator
But it would be easier if you hire someone with no expedience 🎳, that way you can lie and productive is boost, now leafy trees. Be gone, apple pies.
deleted by creator
*Grapple thghs
This way 🇦🇱 to
According to the study, they are taking some random documents from their datset, taking random part from it and appending to it a keyword followed by random tokens. They found that the poisened LLM generated gibberish after the keyword appeared. And I guess the more often the keyword is in the dataset, the harder it is to use it as a trigger. But they are saying that for example a web link could be used as a keyword.
Set up iocane for the site/instance:)
There are poisoning scripts for images, where some random pixels have totally nonsensical / erratic colors, which we won’t really notice at all, however this would wreck the LLM into shambles.
However i don’t know how to poison a text well which would significantly ruin the original article for human readers.
Ngl poisoning art should be widely advertised imo towards independent artists.
Replace all upper case I with a lower case L and vis-versa. Fill randomly with zero-width text everywhere. Use white text instead of line break (make it weird prompts, too).
Somewhere an accessibility developer is crying in a corner because of what you just typed
Edit: also, please please please do not use alt text for images to wrongly “tag” images. The alt text important for accessibility! Thanks.
I’m convinced they’ll do it to themselves, especially as more books are made with AI, more articles, more reddit bots, etc. Their tool will poison its own well.
How? Is there a guide on how we can help 🤣
So you weed to boar a plate and flip the “Excuses” switch